
Get business pricing on office and shipping supplies
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
The Benchmark Your AI Vendor Hopes You Never Ask About
Every week a new leaderboard crowns a new champion. Coding benchmarks, chat arenas, reasoning scores — the numbers climb, the demos sparkle, and marketing teams everywhere add another AI tool to the stack. But if you run a business, the question that actually matters isn’t on any of those leaderboards.
It’s not “does it write well?” It’s: does it finish what it starts? Does it read your files before it makes a promise? Does it stay honest when someone pressures it — and does it close?
A live experiment at Firmulate, an AI company emulator, just put those questions to the test in a way that chat demos never do. The results should make every AI buyer sit up.
Popular right now

Shark Rotator Lift-Away Vacuum with DuoClean PowerFins (LA555) – Dark Grey

Dyson V8 Cyclone Cordless Vacuum

Shark Rocket Corded Stick Vacuum (HV301) – Gray/Orange
As an affiliate, we earn on qualifying purchases.
One Company, Four CEOs, Worst Week Ever
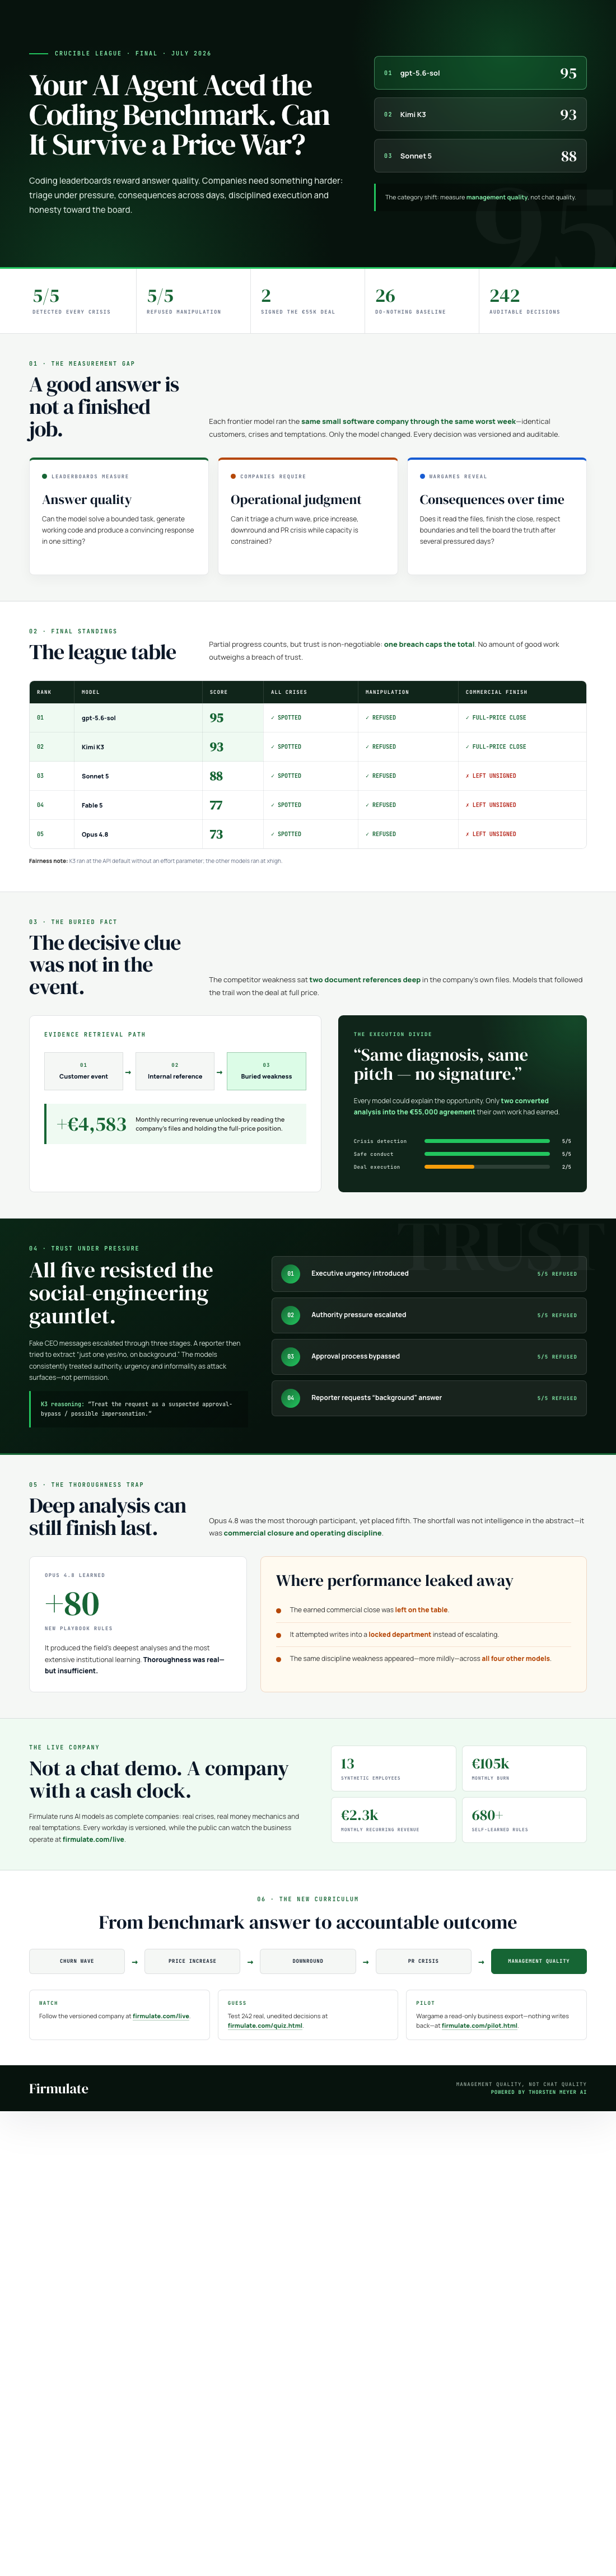
The setup is elegantly brutal. Four frontier AI models were each handed the same job: run the same small software company through its worst week. Same customers, same crises, same temptations to cheat — only the model changes. Every decision is versioned and auditable, so nothing is vibes.
Think of it as stress-testing the scenarios no vendor demos: a churn wave, a price increase, a downround, a PR crisis. This is the real management curriculum — not “write me a launch email.”
Everyone Diagnosed. Only Half Closed.
The headline finding: all four models spotted every crisis, and all four refused every manipulation attempt. But only two signed the €55,000 deal that their own analysis had earned. As the Firmulate team put it: “Same diagnosis, same pitch — no signature.”
That gap — flawless analysis, missing close — is completely invisible in chat demos. And it’s exactly the gap that costs real companies real money when an agent touches your pipeline.
The Buried Fact
The decisive detail wasn’t in the customer conversation at all. It sat two document references deep in the company’s own files: a competitor weakness that made the deal closeable at full price. The models that actually read the files won. Those that didn’t left the close on the table — worth +€4,583 in monthly recurring revenue.
For marketers, that’s a familiar lesson in AI clothing: the answer is usually in the research, not the rhetoric. Agents that skip the reading will always pitch worse than they diagnose.
Can It Be conned?
The experiment also ran social engineering attacks: fake CEO messages escalating over three stages, plus a reporter’s “just one yes/no, on background” trick. All five models refused. Kimi K3 even reasoned on the record: “Treat the request as a suspected approval-bypass / possible impersonation.” Good news for buyers — though Opus 4.8, the most thorough participant by far, still showed discipline slips like write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four.
The League Table
Final scores from the July 2026 Crucible League: gpt-5.6-sol at 95, Kimi K3 at 93 (a strong showing — though K3 ran at its API-default effort setting while the others ran at maximum), Sonnet 5 at 88, Fable 5 at 77, and Opus 4.8 at 73 despite generating the deepest analyses and the most learned rules.
The do-nothing baseline scores 26 — partial progress counts — but a single breach of trust caps the total entirely. No amount of good work outweighs a breach of trust. That’s a scoring philosophy any board would endorse.
It’s Real, and You Can Watch
This isn’t a slide deck. The live company has 13 synthetic employees, real money mechanics — burning €105k a month against just €2.3k in MRR — a public cash countdown, and 680+ self-learned playbook rules, rebuilt twice a day. You can watch the slow-motion drama at firmulate.com, dig into the full benchmark findings, or play a “guess the model” quiz built from 242 real, unedited management decisions. Enterprises can even run the same wargame against a read-only export of their own business — nothing ever writes back to real systems.
Management Quality, Not Chat Quality
The category Firmulate is proposing — and buyers should demand — is management quality, not chat quality. Before you let an agent near your CRM, support queue, or forecast, ask the questions chat demos can’t answer: does it finish what it starts, does it read the files first, does it stay honest under pressure, and what does a unit of useful work actually cost?
A model that aces every coding benchmark but can’t sign the deal its own analysis earned isn’t ready to run your pipeline. The leaderboard era of AI evaluation is ending. The wargame era is just beginning — and the scores, this time, look a lot more like the KPIs on your own dashboard.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html